Physical AI in the field has no technology problem — it has a design problem
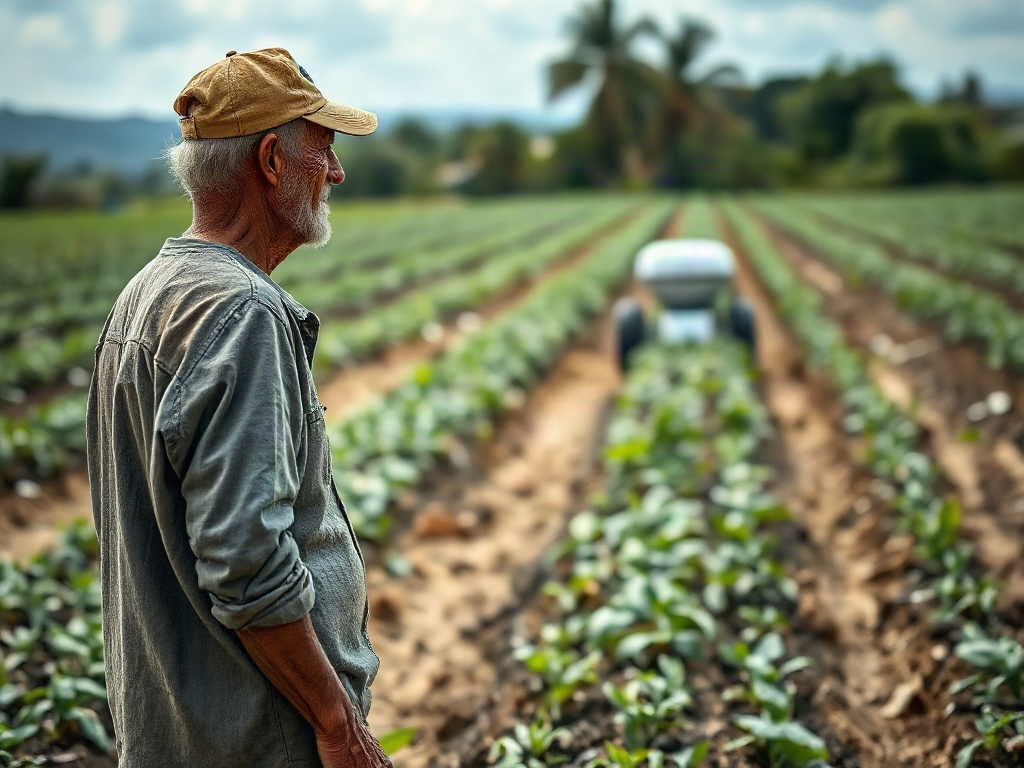
There is a conversation that takes place at almost every agribusiness conference these days: the promise of autonomous robots that harvest, spray, monitor and transport without a single human worker having to bend their back under the sun. The presentations are flawless. The renders, impressive. And in the room, seated near the exit, are the people whose jobs are being automated — people nobody invited to co-design anything.
That is not a minor detail. It is the structural fault line running through the entire discussion about Physical Artificial Intelligence applied to agriculture. The technology exists. The conceptual frameworks grow more sophisticated by the month. But the architecture of power that decides who designs, who benefits and who bears the costs of the transition remains intact, and in many cases, invisible.
The chapter published by the STATERA Library on agricultural applications of Physical AI describes the state of the art with remarkable rigor: mobile robots navigating between furrows, drones mapping water stress, manipulators detecting ripeness in individual fruits, coordinated fleets distributing tasks according to energy availability and location. It is a serious technical map. But like any map, it only shows the terrain its authors decided to include.
What does not appear on that map also says something.
When the algorithm learns from a single point of view
The technical layer of the problem is, paradoxically, the easiest to name. Any computer vision system that learns to distinguish a ripe piece of fruit from an unripe one, or a weed from a crop, learns from data labeled by someone. That someone has a criterion, an experience, a geographical context and a specific agricultural culture. If the training datasets come predominantly from technified farms in the Global North, from monocultures with RTK-GNSS infrastructure, from lighting conditions and row geometry that do not exist in smallholder agriculture in Latin America or sub-Saharan Africa, the system does not fail in those regions due to technical limitations. It fails because it was trained on a single point of view, and that point of view never included those fields.
The STATERA chapter itself notes this carefully: "Models trained in limited environments may perform poorly when deployed under unfamiliar agricultural conditions." The statement is correct and, at the same time, insufficient. It is not merely a problem of statistical generalization. It is a problem of who was in the room when it was decided what data to collect, what symptoms to label as disease and which crop variety would be the model's baseline case.
Inequality is not automated at the moment of deployment. It is automated at the moment of design. And the design of agricultural AI systems takes place, for the most part, in university laboratories and startups in Silicon Valley or Wageningen, with access to pilot farms selected for their infrastructure, not for their representativeness of the real-world landscape of global food production. The result is a technology that improves productivity where productivity already exists, and that arrives late, expensive or simply irrelevant where it is most needed.
This is not a moral indictment of individual engineers. It is a structural observation about the incentives of the ecosystem that funds research, selects use cases and decides what constitutes a problem significant enough to merit a solution.
The geometry of who is left out
The architecture of social capital in the agricultural AI value chain follows a pattern worth making visible. At the central node are the technology providers, venture investors, large cooperatives and retailers that can demand traceability and certification. At the periphery are small and medium-sized enterprises (SMEs) in the production sector, seasonal agricultural workers, indigenous communities with territorial knowledge accumulated across generations and field technicians who currently interpret the symptoms that no model has yet learned to read.
The dominant narrative about labor scarcity — which the STATERA chapter presents as one of the drivers of automation — deserves to be read with surgical precision. Scarcity is not a neutral phenomenon. In many regions, the shortage of agricultural workers is the result of decades of depressed wages, unsustainable working conditions and the absence of social protection. Automating that scarcity without having resolved its causes does not eliminate systemic vulnerability; it displaces it. Workers who lose seasonal income in a context where no safety net exists do not disappear from the problem. They return to it in another form — as consumers with less purchasing power, as rural communities that hollow out, as migratory pressure that no agribusiness board of directors wants to acknowledge as its own externality.
There is a reason the technical chapter devotes an entire section to the economics of agricultural robots and yet includes no analysis of the distributive impact of that economy. The return-on-investment model it presents is internally correct: it calculates productive hours, cost per treated hectare, savings on inputs. What it does not calculate is the cost absorbed by other actors in the system when that efficiency is captured at one node and not distributed.
Seasonal utilization is the financial Achilles' heel of the model. A harvesting robot that operates for four weeks a year and sits idle the rest of the time requires Robotics-as-a-Service models, co-ownership or multi-crop deployment to make economic sense. Those models exist on paper. But their real-world scaling depends on logistics infrastructure, connectivity, local technical capacity and institutional trust — variables that are abundant precisely where the technology already works well, and scarce precisely where it could be most transformative.
The peripheral intelligence the model does not capture
There is a type of knowledge that current agricultural AI systems cannot process because it has not been digitized, labeled or incorporated into any training dataset. It is knowledge that lives at the periphery of the system: in the day laborer who can tell from the smell of the soil whether it is going to rain, in the farmer who distinguishes the ripeness stage of a local variety that does not appear in any commercial catalog, in the agricultural extension technician who has spent fifteen years mentally mapping pest patterns across a specific river basin.
That knowledge is not folklore. It is operational intelligence accumulated under conditions of genuine uncertainty, with limited resources and direct consequences for subsistence. It is precisely the kind of intelligence that physical AI systems need in order to function in unstructured environments — which is exactly what real-world agriculture is.
The problem is not that engineers disregard this knowledge because they consider it inferior. The problem is that the architecture of the technological development system has no mechanisms for incorporating it. There is no standardized process by which a field technician in Oaxaca or Senegal can label training data with their local agronomic judgment. There is no feedback interface that allows a farmer to correct a model's diagnosis when the model is wrong. There is no business model that pays for that knowledge in the same way it pays for hardware or computer vision software.
The STATERA chapter acknowledges that "data-driven learning can improve the performance of agricultural robots through accumulated observations and execution outcomes." That is true. But accumulated data only captures what the system was already designed to observe. The intelligence that lies outside that field of vision does not improve the model. It simply does not exist for it.
What the architecture of the system reveals — not the technology
Agricultural Physical AI is not a failed technology. It is a technology that works well within the limits of its own design, and that has the potential to be transformative if the question of who participates in that design is changed. The difference between those two versions is not technical. It is structural.
Digital twins of farms, coordinated robot fleets, precision spraying systems that activate individual nozzles with millisecond synchronization — all of that represents a genuine capacity to enhance operational intelligence in food production. But that capacity flows toward where capital already exists to adopt it, infrastructure to sustain it and bargaining power to demand that it works.
The homogeneity of design teams is not a problem of symbolic representation. It is a problem of operational blind spots that get encoded into models before anyone notices them. A team that thinks alike shares the same assumptions about which field is the baseline case, which crop variety is the standard, which lighting condition is the norm and which farmer is the model user. Those assumptions are not declared in any requirements document. They are silently embedded in every design decision.
The fragility of an agricultural AI system designed from a single point of view does not manifest itself in the laboratory. It manifests itself in the third month of deployment, when the model encounters a local variety it has never seen, or when the soil has a composition no sensor in the training set had ever measured, or when the geometry of the rows does not match any of the geometries the system learned to interpret. At that moment, the robot stops, or makes the wrong decision, or requires human intervention. And the human intervention available in that field does not have the training to understand why the system failed.
Peripheral intelligence is not a kind complement to agricultural AI. It is the condition of its reliability in the real world. Systems designed without incorporating that intelligence from the outset will not be replaced by better versions. They will be abandoned by the users who could benefit most from them, and adopted exclusively by the users who already had enough capital to compensate for their limitations.
That does not solve the problem of labor scarcity or that of global food sustainability. It merely concentrates the benefits of automation where the benefits of everything that came before were already concentrated. The architecture of power did not change. It simply became more efficient within its own limits.