When programming robots stops being a data problem
There is an implicit bet in most of the capital that has entered robotics over the past three years: that with enough human demonstrations, robots will learn to do what humans do. The logic is seductive because it already worked once, with language models. But robotics is not text, and that difference is beginning to cost those who assumed the same recipe would produce the same result.
What UC Berkeley and NVIDIA presented at the 2026 Conference on Robot Learning is not an incremental improvement on that paradigm. It is a break with it. The proposal they have called agentic robotics argues that the problem was never a lack of data, but that the wrong bottleneck was being attacked.
The plateau nobody wanted to announce
Ken Goldberg, professor of robotics at UC Berkeley and co-founder of Ambi Robotics, has spent years working with industrial manufacturers, including Siemens and Bosch. His diagnosis is straightforward: imitation learning works up to a point, and that point arrives faster than investors expected. "You get good performance with data at the beginning, but then things go wrong. You add more data. But then other things go wrong," he explained. There is no clear signal that the system is converging.
The underlying problem is structural. Language models were trained on a significant fraction of all the text humanity has ever produced. No robotics dataset comes close to that scale, and building one physically—through human demonstrations recorded in real environments—is a slow and costly process. Companies that raised capital on the premise that data would solve everything are now facing an uncomfortable question: how much more is needed, and whether that "enough" will ever arrive before the market's patience runs out.
What further complicates the diagnosis is that imitation learning produces systems nobody can easily audit. They are high-average-performance black boxes that can fail in unpredictable ways at the least convenient moment. For industrial applications, where "failure" can mean a production line brought to a halt or an injury, that risk profile is difficult to justify before an operations committee.
Code instead of data: the pivot proposed by Berkeley and NVIDIA
Agentic robotics converts the data-scarcity problem into a code-generation problem. And for that, language models do have sufficient scale.
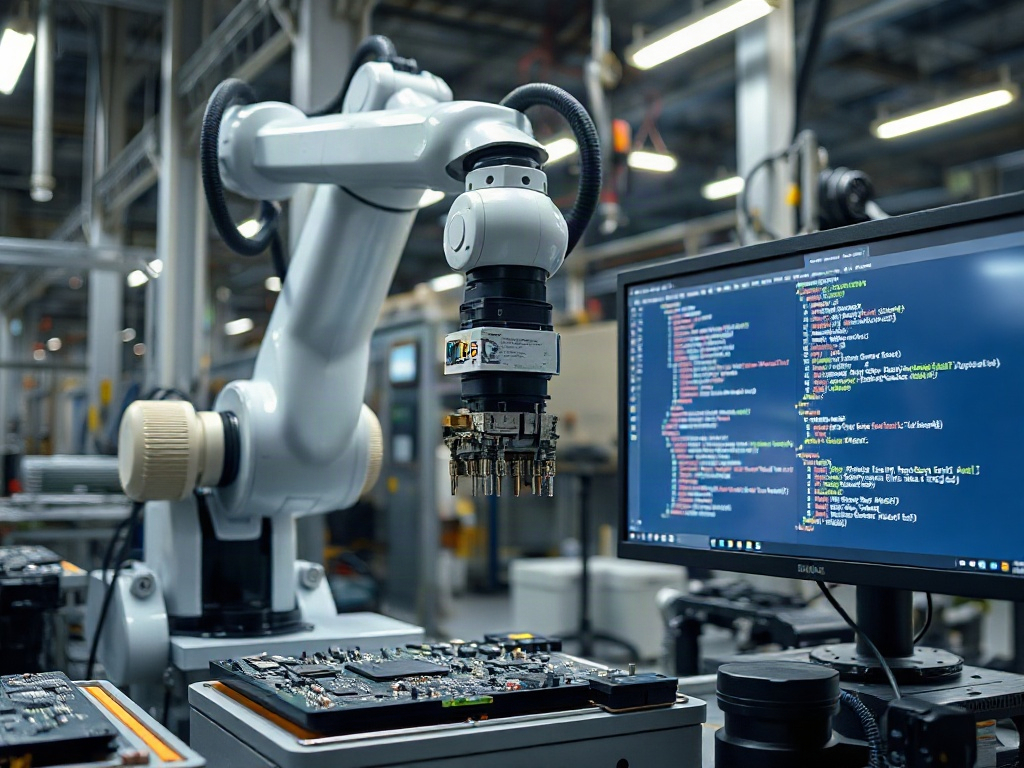
The workflow operates as follows: a goal expressed in natural language—such as packing products into a bag or depositing syringes into a waste container—is broken down into subtasks. Specialized code agents, autonomous AI systems capable of writing, testing and modifying software, take charge of specific functions: visual perception, pose estimation, motion planning, gripper control. Each agent uses the already-existing robotics libraries, which represent decades of development in object classification, trajectory planning and motion control. The resulting code is executed in simulation, the agents identify failures, adjust parameters and iterate again.
The results documented in Berkeley's tests reached success rates of up to 99% on the evaluated tasks, compared with roughly 20% for imitation-learning methods on those same tasks. The gap is not marginal.
One dimension that deserves attention is the simulation itself. Configuring a simulated environment with sufficient precision for the generated code to be useful in the physical world has historically been a manually intensive task. What Goldberg and his team demonstrated is that an agent can adjust the simulator's parameters—lighting, geometry, background—to match a video of the real environment. Goldberg's description was vivid: "It gave us chills. Comparing side by side, it was very hard to distinguish the simulation from the video." That does not solve the physical transfer problem, but it eliminates a layer of engineering work that previously required specialists.
The architecture also includes a quality-control layer: an adversarial agent designed to find flaws in what another agent produces. Spencer Huang, director of robotics engineering at NVIDIA, described it with pragmatism: "We all know that AI agents can produce garbage. To counteract that, we use adversarial setups." It is a way of incorporating skepticism into the process itself—not as an external correction but as part of the development cycle.
What holds up in manufacturing and what still does not work outside it
The most concrete case to emerge from the research involves Wistron, the Taiwanese manufacturer of GPU motherboards for NVIDIA. When that company incorporates a new product into its line, reconfiguring a single robot takes a minimum of eight hours. With agentic robotics, Huang says that time drops to one or two minutes. If that figure holds in real production, the impact is not merely operational but financial: shorter production runs, higher equipment utilization, and the ability to respond to product changes that today require weeks of advance planning.
The other example Huang cites is the semiconductor industry, where some assembly processes require placing components with a precision of 0.3 millimeters. That is a threshold that well-programmed conventional industrial robots can meet. It is not a threshold that current humanoid robot platforms can reach with the repeatability that industry demands. For that use case, agentic robotics offers something that general-purpose humanoid bets still do not: demonstrable reliability under conditions of extreme precision.
That is where Torsten Kroeger, chief scientist at Intrinsic—Alphabet's robotics company—applies the most rigorous technical brake. His argument is not that the approach is wrong, but that the problem of physical contact is not solved by any existing physics engine. A simulation can look identical to reality; that does not guarantee that mechanical behavior—friction, deformation, impact—is modeled with the fidelity a robot needs to manipulate objects under real industrial conditions. That gap is not closed by model agency; it is closed by the simulator's physics. And on that front, the entire field remains behind.
Kroeger also raises something that will have regulatory consequences before the sector has resolved it conceptually: if agents generate and modify robot code autonomously, how can it be established that that code is always safe. The argument is not that agents will fail, but that as the scale of autonomous modifications grows, human review becomes progressively less feasible. That is the alignment problem transposed to physical manufacturing, and it carries far more concrete consequences than it does in pure software.
The most interesting argument is not performance: it is the architecture of value
The benchmark results are the easiest part to communicate and probably the least relevant for deciding whether this direction has a future in production. What matters more is a thesis that Huang put forward toward the end of his presentation and that deserves careful examination.
His argument is that general intelligence in robotics will arrive first in the form of an agent that orchestrates conventional technologies and specialized policies, not as a single model that learns everything from scratch. To the outside observer, the result looks like general intelligence because the agent coordinates everything coherently. Underneath, there are well-defined components doing what they know how to do.
That has implications for how value is distributed across the industry. NVIDIA is not betting solely on selling compute to train robots. It is betting that the development process—simulation, code generation, validation and robot retasking—will run through its software infrastructure. Isaac Lab-Arena, the Newton physics engine, the robotics libraries: if the agents that generate code for robots use those tools by default because they are available and well-documented, NVIDIA becomes the standard development layer for the industry, not merely a chip supplier.
There is also a feedback argument that Huang mentioned explicitly: the code generated by agents for robots can become training data for the next generation of models. If that holds, agentic robotics does not only solve today's data-scarcity problem. It creates a mechanism to generate data at scale, with high quality and clear semantic structure—something that human demonstration data rarely has.
The real risk is not that the approach fails to work in simulation. There is already evidence that it does. The risk is the one that always accompanies bets that are technically correct but premature in their transfer to the physical world: that the distance between the laboratory and the production line consumes the competitive advantage before the market can validate it. Manufacturers evaluating this are not buying a paper with a 99% success rate in simulation. They are buying demonstrated reliability in their own plant, with their own robots, their own materials and their own tolerances. That validation is still pending, and it is what will decide whether this direction becomes the standard or remains one more iteration on the road toward something that has yet to be defined.